Crawl Budget Experiment: 9 Stuck URLs, Zero Manual Indexing Requests
On July 25, 2026, nine posts on this blog were sitting unindexed. One had been live for 17 days without Google fetching it once. Another was in the worst state ..

All Posts · 5
On July 25, 2026, nine posts on this blog were sitting unindexed. One had been live for 17 days without Google fetching it once. Another was in the worst state ..

A blog sitemap is an XML file listing the URLs on your blog you want search engines to know about. One rule governs the whole thing: list only canonical, indexa..

A robots.txt file for a blog tells crawlers which paths they are allowed to fetch. It lives at one fixed location, yourdomain.com/robots.txt, and every well-beh..

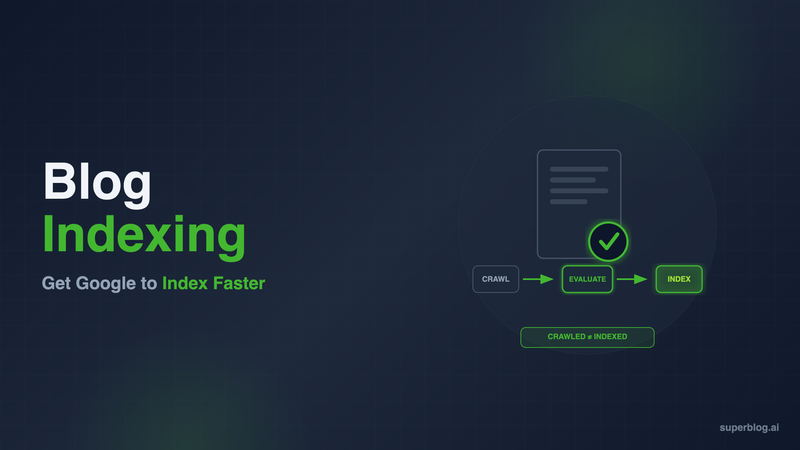
Blog indexing is the process where Google adds your published post to its searchable index after crawling it. Crawling and indexing are not the same thing. Goog..

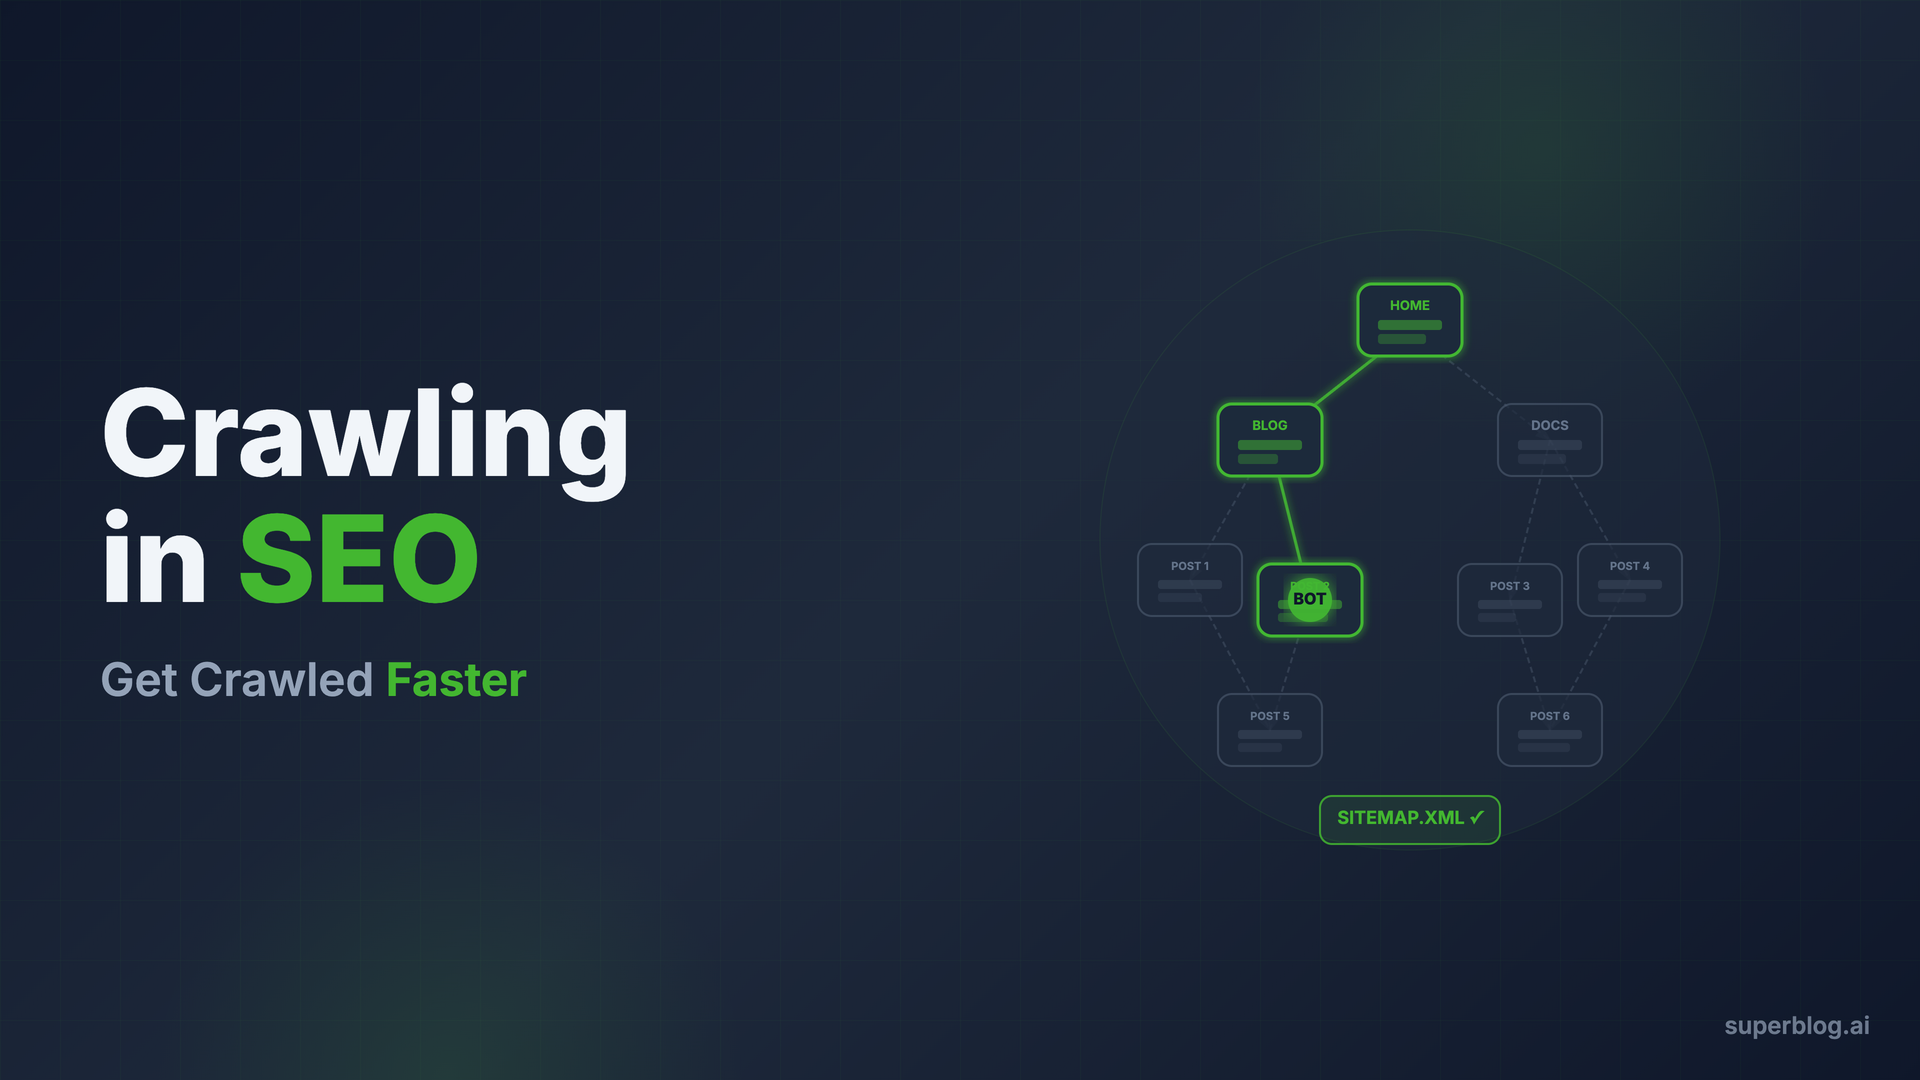
Crawling in SEO is the process by which search engine bots systematically discover and fetch pages from the web. If a page is not crawled, it cannot be indexed...

Loading...